Core platform

4S CoreAstrum: GenAI Foundation. Build Faster. Operate with Confidence. Power Enterprise AI.

Everything you need to build, run and scale enterprise AI, in one platform.

The intelligence layer your enterprise runs on.

  • Knowledge & pipelines
  • Agents & copilots
  • Guardrails & evaluation
  • Enterprise-ready
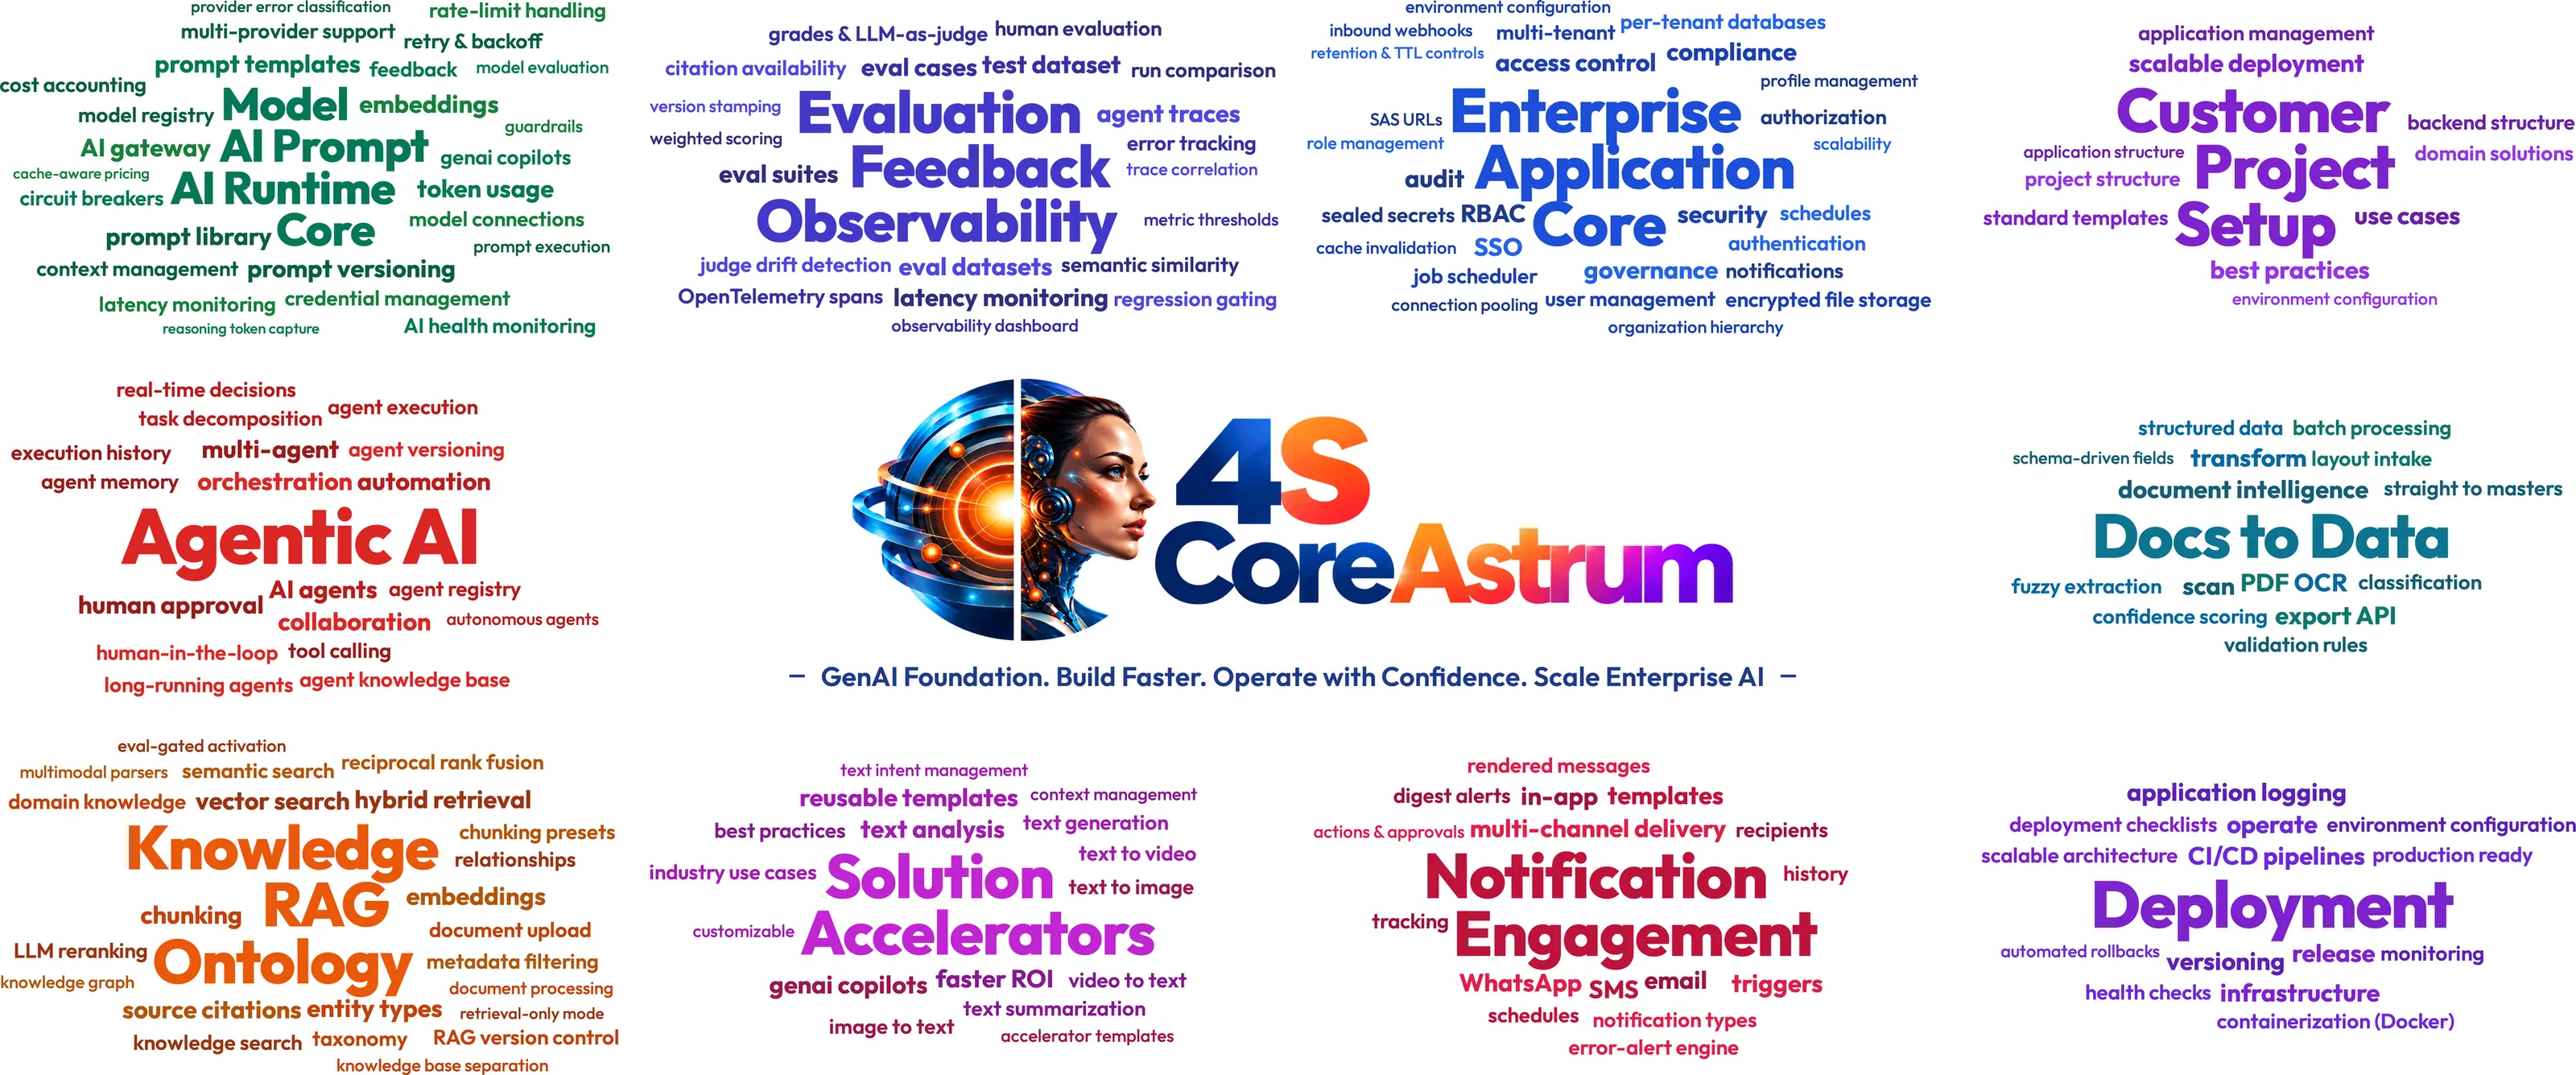
4S CoreAstrum capability map: Enterprise Application Core, Knowledge, RAG and Ontology, Agentic AI, Model, Prompt and AI Runtime Core, Evaluation, Feedback and Observability, Docs to Data, Solution Accelerators, Notification and Engagement, Customer Project Setup and Deployment
The complete platform: ten modules, one foundation. View full size

Anyone can demo AI. Running it in production is the hard part.

Grounding, guardrails, evaluation, access, cost and observability are the difference between a prototype and production AI. 4S CoreAstrum provides all of it as one foundation, so your teams ship trusted AI instead of rebuilding the plumbing for every project.

  1. Ingest
  2. Retrieve
  3. Reason
  4. Guard
  5. Observe
  6. Improve

From your data to a trusted answer.

Every stage builds on the one before it, so an assistant is grounded, guarded and observable by default, not as an afterthought.

  1. 01

    Ingest

    Connect documents, databases and APIs; chunk and embed into vector search.

  2. 02

    Retrieve

    RAG fetches the most relevant context for each question.

  3. 03

    Reason

    Agents and copilots plan, call tools and draft the answer.

  4. 04

    Guard

    Guardrails check grounding, safety and policy before it ships.

  5. 05

    Observe

    Trace, evaluate and monitor every response.

  6. 06

    Improve

    Feedback and evaluation tune quality over time.

The AI engine, already built.

Six production-hardened AI modules, configurable per deployment and shared by every assistant, agent and copilot you build.

Answers grounded in your own data

Knowledge, RAG & Ontology

Documents are parsed, chunked and embedded; hybrid retrieval with reciprocal rank fusion and LLM re-ranking finds the right context; every answer cites its sources. An ontology and knowledge graph capture your domain's entities and relationships.

  • hybrid retrieval
  • vector search
  • reciprocal rank fusion
  • LLM reranking
  • source citations
  • knowledge graph
  • entity types & taxonomy
  • multimodal parsers
  • RAG version control
  • eval-gated activation

Agents that plan, act and collaborate

Agentic AI

AI agents decompose tasks, call tools and take action, alone or as a multi-agent team, with memory, their own knowledge base and a full execution history. Human approval steps keep people in control of the decisions that matter.

  • multi-agent orchestration
  • task decomposition
  • tool calling
  • agent memory
  • agent registry & versioning
  • human-in-the-loop
  • long-running agents
  • real-time decisions

One gateway to every model

AI Runtime: Models & Prompts

An AI gateway routes across providers and models from one registry, with managed credentials and a versioned prompt library. Guardrails run on every call, and resilience is built in: circuit breakers, retry with backoff and rate-limit handling.

  • AI gateway
  • multi-provider support
  • model registry
  • prompt versioning
  • guardrails
  • token usage & cost accounting
  • cache-aware pricing
  • reasoning token capture
  • circuit breakers
  • AI health monitoring

Know how good every answer is

Evaluation, Feedback & Observability

Eval datasets and suites, LLM-as-judge with judge drift detection and human evaluation score quality before and after release. Regression gating blocks a worse version, and OpenTelemetry traces show every step of every agent run.

  • eval suites
  • LLM-as-judge
  • judge drift detection
  • human evaluation
  • regression gating
  • run comparison
  • OpenTelemetry spans
  • agent traces
  • latency monitoring
  • observability dashboard

From scans and PDFs to validated data

Docs to Data

OCR and layout intake read scanned documents and PDFs; schema-driven extraction pulls out fields with a confidence score, validation rules check them, and batch processing sends clean data straight to your master records.

  • PDF OCR
  • layout intake
  • classification
  • schema-driven fields
  • fuzzy extraction
  • confidence scoring
  • validation rules
  • batch processing
  • export API

Start past the plumbing

Solution Accelerators

Reusable templates and GenAI copilots for common jobs: text analysis, generation and summarization, and conversions between text, images and video, packaged with industry use cases and best practices for a faster ROI.

  • GenAI copilots
  • text generation
  • text summarization
  • text to image
  • text to video
  • video to text
  • image to text
  • accelerator templates
  • industry use cases

Every request, traced end to end.

See exactly how each answer was produced: prompt and session, knowledge base, pipeline, agent and every model call, with tokens, latency and cost at each step, across models run with different parameters.

Execution trace1 request · 6 steps · 2 models
  • Prompt · user session12 ms
  • Knowledge base · RAG · 1.2k tok64 ms
  • Pipeline · 3 steps38 ms
  • Agent · 2 tool calls52 ms
  • Model · gpt-4o · temp 0.2220 ms
  • Model · claude · temp 0.7160 ms
Total2 models · 1.9 s · 3.1k tokens · $0.011

Full observability, not guesswork. Compare models and parameters side by side, watch tokens, latency and cost per call, and replay any session end to end.

Enterprise engineering, built in.

Security, tenancy, error handling and alerting are part of the platform, not a project. Every AI product on 4S CoreAstrum inherits them.

Enterprise Application Core

Security, access & RBAC

Roles and permissions per workspace, single sign-on, organization hierarchies and a full audit trail. Access is always decided centrally, so a misconfigured tenant can never lock a valid user out.

  • RBAC
  • SSO
  • role management
  • organization hierarchy
  • audit & compliance
  • sealed secrets
  • encrypted file storage

One platform, every tenant kept apart

Multi-tenancy & scale

Each tenant's data, vectors, prompts, keys and audit are separated by default, in a shared database or one per tenant. Connection pooling, caching and a job scheduler keep it fast as usage grows.

  • multi-tenant
  • per-tenant databases
  • connection pooling
  • cache invalidation
  • retention & TTL controls
  • job scheduler
  • inbound webhooks

Problems found before users report them

Error tracking & alerting

Errors are logged, classified and routed. An error-alert engine and digest alerts notify the right people, AI provider errors are classified automatically, and AI health is monitored continuously.

  • error-alert engine
  • digest alerts
  • error tracking
  • provider error classification
  • AI health monitoring
  • application logging

The right message, on the right channel

Notification & engagement

One engine sends templated messages by email, WhatsApp, SMS and in-app, on triggers or schedules, with approval actions, delivery tracking and a full history.

  • multi-channel delivery
  • email · WhatsApp · SMS
  • in-app
  • templates
  • triggers & schedules
  • actions & approvals
  • tracking & history

From project setup to production.

A standard delivery lifecycle for every customer project, so each new AI product starts from proven templates and ships through the same gates.

  1. 01

    Set up

    Standard templates, project and backend structure, environment configuration.

  2. 02

    Build

    Reusable accelerators and best practices for each domain solution.

  3. 03

    Evaluate

    Eval suites and regression gating before anything ships.

  4. 04

    Release

    CI/CD pipelines, release versioning, deployment checklists, Docker.

  5. 05

    Operate

    Health checks, monitoring, application logging, automated rollbacks.

Runs where your data and models live.

Choose where AI runs, which models it uses, and how it's governed, per deployment, by configuration.

On-prem, cloud or air-gapped

Run the whole pipeline beside your data; nothing has to leave the building.

Any model, hosted or API

Bring your own LLM and embeddings; swap or route models without rewrites.

Your data stays put

Retrieval and grounding run where your data lives, not in someone else's cloud.

Every AI call traced

Prompts, retrievals, tools and responses are logged for review and evaluation.

Access that can't lock out

Access is always checked centrally, so a misconfigured tenant never blocks a valid user.

Marketplace-ready

A consistent brand layer and packaging built for distribution, including Google Marketplace.

One foundation. Every kind of AI.

Teams build a wide range of AI on the same foundation, each grounded in your data, guarded, and observable from day one.

RAG assistants

Grounded question-answering over your own documents and data, with citations back to the source.

AI agents & copilots

Assistants that plan, call tools and take action across your systems, with a human in the loop.

Document processing

Docs-to-data processing that turns unstructured files into clean, structured data.

Chat sessions

User chat with saved sessions, history and memory across conversations.

Agentic workflows

Multi-step automations that reason across your tools and systems.

Live monitoring & signals

AI that watches streams and sources, and surfaces what matters in real time.

Built for production AI

Grounded answers. Trusted agents. Enterprise-ready.

Bring retrieval, models, guardrails, observability and access into one AI foundation, and give every assistant a head start.